A missing ranking is a reason to inspect the page before rewriting its title. Choose a product page, collection, or article and note its URL. Has the search system found it, fetched it, read the core content, and indexed it? Once those states are clear, inspect queries, impressions, and clicks.
16 parts · 3 checkpoints
Show all 16 parts
- 01Work it out: which of four URLs can actually be indexed
- 02Think of a search engine as an inspector who does not shop
- 03Crawl-to-rank state map: identify the state before choosing an action
- 04After indexing, use four evidence areas to choose the next check
- 05Confirm the URL state before choosing a fix
- 06Practice the state check with a new collection page
- 07Different evidence answers different questions
- 08Follow the checks from URL discovery to user clicks
- 09Record the search state for one URL, has a checkpoint
- 10Record evidence for each search stage
- 11Choose the first check based on site history
- 12Four versions of “no ranking,” four first checks
- 13Quick check, has a checkpoint
- 14What to confirm before moving to the next lesson, has a checkpoint
- 15Next reading
- 16Check these six points before moving on
A newly published tumbler collection shows how to choose the evidence and next action. You can start here directly. If you have the previous lesson’s page map, choose one important page from it.
Key point In one line
Work it out: which of four URLs can actually be indexed
Four URLs from one store (example data). Rule: canonical points at itself and there is no noindex; those two are enough for a URL to be indexed, while a robots block does not prevent indexing, it only limits what the crawler can read. Submitting a sitemap changes nothing.
Three conditions for four URLs
| Item | URL | Canonical self | Crawl allowed | noindex set |
|---|---|---|---|---|
| A | /products/leak-proof-bottle | Yes | Yes | No |
| B | /products/leak-proof-bottle?variant=2 | No: points at the main product | Yes | No |
| C | /pages/dog-hydration-guide | Yes | Yes | Yes |
| D | /blogs/news/best-dog-bottle | Yes | No: blocked by robots | No |
Decide before you read on. Say which URLs can be indexed and why submitting to a sitemap does not change the answer.
Answer key: A and D can both be indexed; B and C cannot. B hands its indexing signal to the main product page through canonical, and C asks explicitly not to be indexed. D is the one most often got wrong: with crawling blocked, a search engine can still index the URL from links alone, only without content or a snippet, which is why removing a page from the index takes noindex and not robots. A sitemap only says the URL exists; it never decides indexing.
Think of a search engine as an inspector who does not shop
Compare the four symptoms, then choose an inspection action, then compare what a buyer sees with what a search engine can prove. That keeps indexing, impressions, and click problems from turning into title edits or keyword stuffing.
Think of a search engine as an inspector who does not shop
Not found
- Symptom
- The page exists in the store admin but has no stable site entry path; the current report does not yet confirm its discovery state.
- Check first
- Start with sitemap, navigation, collections, related articles, product links, and the discovery state in URL Inspection.
- Do not assume
- This is not a title-copy problem. Search systems may not know the URL exists yet.
Not fetchable
- Symptom
- You can open the page in a browser, but search systems may be blocked by robots, login, bad status, redirect chains, or slow response.
- Check first
- Paste the full URL into the Search Console URL Inspection bar, run live test, then check crawl allowed, page fetch, status code, and redirects.
- Do not assume
- This is not a keyword problem. First prove Google can fetch the current page reliably.
Not understood
- Symptom
- The storefront screenshot looks complete, but source or rendered HTML misses core products, copy, pagination, filters, or canonical signals.
- Check first
- Compare page source, the rendered page in URL Inspection, View crawled page, and the latest visible page-content change.
- Do not assume
- Publishing more articles will not solve this. Make the core content reliably visible first.
Not worth serving yet
- Symptom
- The page may be crawled or indexed and still have no impressions because of duplication, thin value, conflicting primary-version signals, or a mismatch with its intended queries.
- Check first
- Check Indexing Pages, Google-selected canonical, noindex, duplicate URLs, Search Console Pages / Queries, and competing SERP pages.
- Do not assume
- Only now discuss page value, intent, internal support, title/snippet, and competition. Do not treat every unindexed URL as a technical bug.
Think of a search engine as an inspector who does not shop
- First check
- First check whether the URL appears in the sitemap, navigation, collections, related articles, or product links.
- What the buyer sees
- A buyer may arrive from home, a collection, an article, or an ad and see a collection page with 12 products, knowing the page exists.
- What the search inspector can prove
- A search engine does not browse like a shopper. It is more like an inspector who follows sitemaps, navigation, internal links, and external links to find URLs.
- Do not misread it this way
- Changing the title before the page has entry paths is like repainting the sign while the inspector still cannot find the address.
- First check
- Use URL Inspection live test, robots.txt, status code, and redirect chain to confirm crawlability.
- What the buyer sees
- A buyer can open the page in a browser and may assume the page is fine.
- What the search inspector can prove
- The inspector still checks HTTP status, robots rules, redirects, server response, and login barriers.
- Do not misread it this way
- Saying “Google should see it because I can open it” is one of the most common beginner misreads.
- First check
- Copy proof from page source / rendered HTML: core title, product list, explanatory copy, and internal links.
- What the buyer sees
- A buyer sees product images, prices, specs, copy, and filters.
- What the search inspector can prove
- The inspector compares source and rendered HTML to see whether core copy, product lists, pagination, and internal links appear reliably.
- Do not misread it this way
- Looking only at the storefront screenshot can turn a rendering issue into a fake keyword issue.
- First check
- Check Indexing Pages, Google-selected canonical, noindex, duplicate URLs, and the page job.
- What the buyer sees
- A buyer only cares whether the page answers the question or helps the purchase.
- What the search inspector can prove
- A search engine also judges whether the page is duplicate, thin, canonically conflicted, or not worth indexing.
- Do not misread it this way
- Publishing more similar content after “crawled but not indexed” may only amplify duplication.
Crawl-to-rank state map: identify the state before choosing an action
First identify the URL’s current state, then record the evidence and next action. The team’s diagnostic sequence covers discovery, crawling, rendering, indexing, serving, and post-click fit. The last is a business review, not a stage of Google’s search processing. Google does not guarantee that every URL will be crawled, indexed, or shown. Crawled does not mean indexed, and indexed does not mean shown for a query.
Crawl-to-rank state map: identify state before action
Discovery
- This stage asks
- Search systems first need to know that this URL exists.
- Evidence
- Sitemap, navigation, collections, article links, external links, URL Inspection.
- Common blocker
- The page is orphaned and has no stable internal entry point.
Crawling
- This stage asks
- Search systems request the URL and read status, HTML, links, and base signals.
- Evidence
- URL Inspection, robots.txt, HTTP status, redirect chain, server logs.
- Common blocker
- Blocked by robots, login, error statuses such as 404/500, slow response, or redirect chains.
Rendering
- This stage asks
- If core content depends on JavaScript, the system needs to see the rendered page.
- Evidence
- URL Inspection live test, rendered HTML, HTML source, whether key content is visible.
- Common blocker
- Products, body copy, internal links, or title signals only appear after complex JavaScript.
Indexing
- This stage asks
- The system decides whether the page is worth putting in the index.
- Evidence
- Pages report, URL Inspection, canonical, noindex, duplicate content, page quality.
- Common blocker
- The page is duplicate, thin, unclear, canonicalized elsewhere, or noindexed.
Ranking / serving
- This stage asks
- Only after indexing does the page compete for specific queries.
- Evidence
- Search Console queries, impressions, average position, competing pages, internal-link support.
- Common blocker
- Intent mismatch, strong competition, weak title/snippet, or insufficient internal support.
Click / post-click fit
- This stage asks
- After impressions, judge whether searchers click and whether post-click behavior continues.
- Evidence
- CTR, title/snippet, page behavior, add-to-cart, inquiries, orders, refunds, support questions.
- Common blocker
- The SERP promise is unclear, or page fit, product, price, or trust path breaks.
The page has no ranking. Which layer is it actually stuck at?
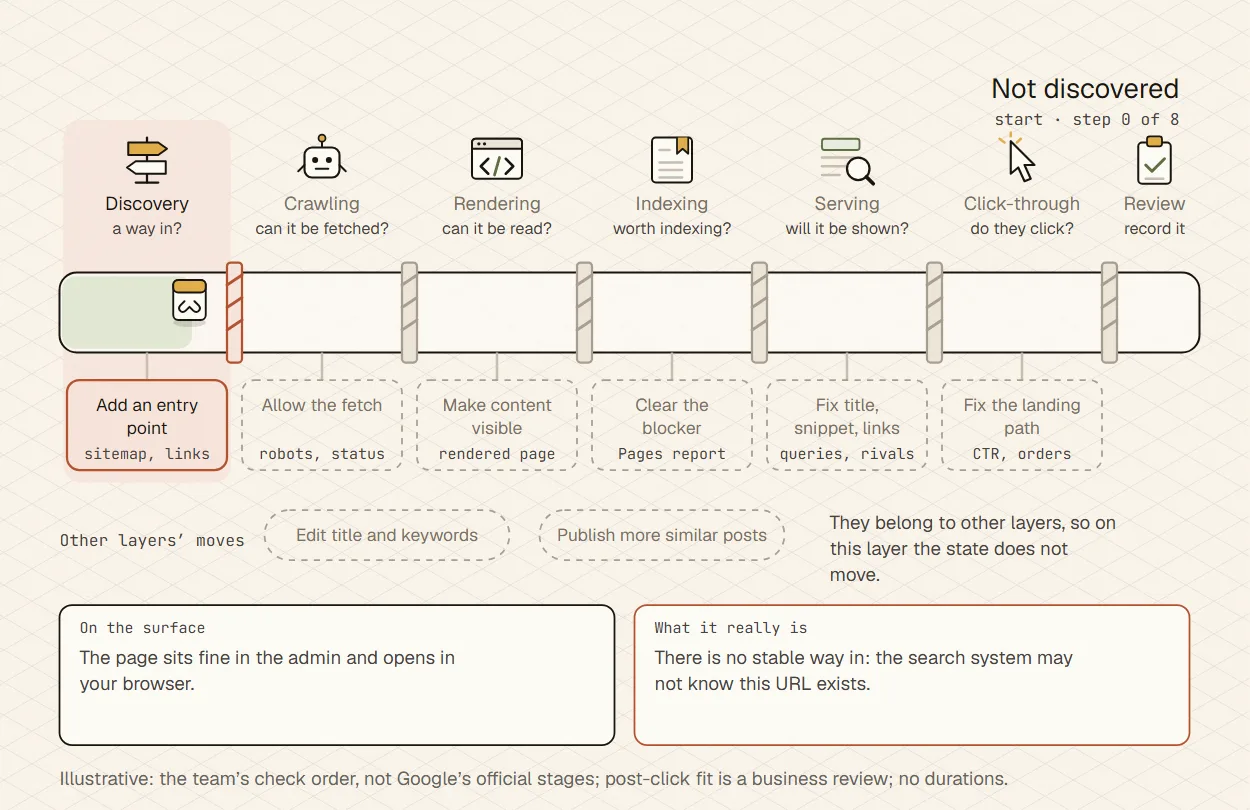
As text: the whole walk-through
- Not discovered However good the new title and keywords are, this layer is not passed and the URL stays where it is.
- Not crawled Put the URL in the sitemap, navigation or related internal links: only then is discovery passed.
- Not rendered Open up robots, login, error statuses and redirects, then read back: it can be fetched, but not yet proven readable.
- Not rendered However many articles are published, this layer is not passed and the state does not move.
- Not indexed Products, copy and links now appear reliably in the rendered page; crawled does not mean indexed.
- Not shown Check noindex, canonical, duplicates and page quality, and deal with the real blocker.
- Not clicked Look at the query and rival pages: intent, title, snippet and internal support. Now an edited title fits.
- Back to review The product, price and trust path after the click belong to the business review; record all six layers, then review.
Illustrative: the team’s check order, not Google’s official stages; post-click fit is a business review; no durations.
For a newly published collection, write “discovery to confirm,” not “SEO failed.” Let URL Inspection, internal entry paths, and Search Console state supply the facts before moving it to crawl, index, or serving. At review, you can check whether the original diagnosis held and which change needs further investigation.
After indexing, use four evidence areas to choose the next check
Ranking is not one “edit the title” button. Use intent match, content quality, structural clarity, and trust and usability to connect a result-page symptom to evidence and an action; they guide the next judgment but cannot guarantee ranking or indexing.
Four evidence areas help choose the next check
Intent match
- Ask
- Does this page complete the job behind the query instead of repeating the query words?
- Observable evidence
- Compare the query, SERP result type, page job, and first-screen promise together.
- Next action
- Name the query scene the page serves, then align its structure and promise to that scene.
Content quality
- Ask
- Can a reader get a complete, distinctive answer that is useful for a decision?
- Observable evidence
- Check core facts, distinctive explanation, product or case detail, common questions, and duplicate-page signals.
- Next action
- Fill the missing answer or consolidate duplication; do not substitute word count for useful information.
Structural clarity
- Ask
- Can both search systems and readers quickly see the topic, hierarchy, and related entry paths?
- Observable evidence
- Compare heading hierarchy, descriptive anchor text, internal links, rendered HTML, and click depth.
- Next action
- Give one page job clear headings, sections, and related links. For this exercise, map 5–10 important pages; that is a practice range, not an eligibility threshold or quota for doing SEO.
Trust and usability
- Ask
- Does the page feel trustworthy and usable, including readable copy and a workable mobile experience?
- Observable evidence
- Check author or source context, key facts, policies, and contact paths, then test mobile readability, scrolling, and the main action.
- Next action
- Add trustworthy support, fix unreadable layout and mobile blockers, and write the experience issue as a reviewable metric.
Site structure and internal links work together. A common path is for the home page to link to major category or topic pages, which link to more specific collections, product pages, and articles. Related pages should link naturally, and important pages should not sit many clicks deep. Disconnected articles, important pages reachable only through site search, and a topic split into many thin pages make it harder to find pages and understand their relationships.
An internal link has three jobs: help search systems discover a page, show how topics relate, and help readers move to the next useful page. New pages especially need a path from an existing collection, category, or related piece of content.
Only after a meaningful fix should you submit one Request indexing request, record the request date , and review later. It is not proof of ranking and not a guarantee of indexing .
Confirm the URL state before choosing a fix
Click different symptoms. This module is not about memorizing the pipeline; it trains you to turn no ranking into a verifiable state: what evidence to inspect, where the blocker likely sits, and which layer to fix next. After clicking, put the diagnosis into the URL search-state review record below.
What state is the URL in? Wrong state means wrong fix
URL Inspection or Search Console does not yet have enough information to confirm discovery.
- Look first
- Sitemap, internal links, navigation, and whether the page is orphaned. A missing report entry does not prove that the system has never found it.
- Likely blocker
- There may be no stable entry path, or the current report may lack a usable discovery record.
- Next action
- Check internal links and sitemap coverage, then set a review date. Do not edit the title first.
The page was visited but did not enter the index.
- Look first
- Page quality, duplicate content, canonical, noindex, whether it deserves its own URL.
- Likely blocker
- Low value, duplication, or conflicting canonicalization signals.
- Next action
- Decide whether to strengthen, merge, canonicalize, noindex, or remove; do not only publish more.
Search Console has no impression record for the selected page, queries, and date range. This does not prove that demand is zero.
- Look first
- Confirm the page and date range, then check queries, country, device, average position, the live SERP, page job, internal links, and customer questions.
- Likely blocker
- Review query context, page type, relevance, internal support, and competition. No impressions alone do not show that nobody searches.
- Next action
- Record “no impressions observed” separately from “impressions with few clicks.” Use SERP, customer questions, and other demand evidence before deciding whether this page should serve the task.
The page appears in results, but searchers do not choose it.
- Look first
- CTR, title link, snippet, SERP layout, page promise.
- Likely blocker
- Title/snippet does not explain why to click, or intent and promise mismatch.
- Next action
- Adjust title and first-screen promise, then keep a review window.
SEO brings visits, but users do not continue, add to cart, inquire, or order.
- Look first
- Page behavior, price, trust information, CTA, inventory, support questions.
- Likely blocker
- The problem may no longer be search; it may be page fit and business conditions.
- Next action
- Route to CRO, product-page, pricing, or support-path review.
After choosing a symptom, check its first evidence source, then record an owner and review date. No query or impression row in Search Console does not prove that there is no market demand.
Practice the state check with a new collection page
A new collection has no organic traffic after 10 days. First prove which layer is stuck.
An indexable asset is a page with a distinct user job that can be discovered, understood, indexed, and used for a query; in Shopify, it is often a collection, product page, or article. A page loading in a browser only proves that a shopper can visit it—not that a search system has seen, understood, or chosen to show it.
Case: summer travel tumbler collection
Ten days after launch, the team says “SEO is not working.” It still does not know whether the collection was discovered, crawled, fully rendered, indexed, or indexed without entering a meaningful query. Rewriting the title or publishing a similar article now may only hide the real blocker.
Result interpretation: ten days is a signal to inspect, not a failure verdict. Until the state is known, “no traffic” cannot be assigned to keywords, technical setup, or content quality.
The interactive choices above only practice diagnostic order; they do not read your Search Console. It becomes a reviewable SEO record after the page label or non-sensitive path, state, evidence, next action, owner, and review date are written into the notes below.
Turn one URL check into a reviewable record
Map important pages and their links
For this exercise, choose 5–10 important pages and note how they connect. Use the pages the store actually has; a smaller store does not need to fill a quota.
How to confirm
This is a practice range, not a threshold for starting SEO.Choose pages that need checking
Mark at least three possible orphan, duplicate, or low-value pages as candidates. Do not decide to remove or redirect one from appearance alone.
Keep as evidence
Candidate labels guide research; confirm each page’s job, duplicates, and business use before acting.Use evidence for the same URL
Check its entry path, URL Inspection’s indexed version, and the live test. Then separate crawling, rendering, indexing, query impressions, and post-click fit.
How to confirm
A passing live test does not prove indexing, and a missing impression record does not prove zero demand.Inspect rendered content when needed
If the page depends on JavaScript, compare source with the tested or crawled page. Confirm that core copy, products, and links appear reliably.
Keep as evidence
Ask a technical owner to investigate rendering only when the key content remains missing from source or stable rendered output.
Different evidence answers different questions
Each source answers a different question. Do not call everything no ranking.
Evidence sources
| Item | Evidence source | What it can answer | What it cannot prove alone |
|---|---|---|---|
| URL Inspection | URL Inspection | The indexed version, live test, page fetch, crawl allowed, rendered page, and canonical status for one URL. | A passing live test does not mean the page is already indexed, ranked, or receiving traffic. |
| Sitemap | Sitemap | Whether important URLs were submitted to search systems. | Does not replace internal links or guarantee indexing. |
| Internal links / navigation | Internal links / navigation | Whether the page has a site entry and is treated as important. | Does not alone prove the page is high quality. |
| robots / noindex / canonical | robots / noindex / canonical | Whether crawling, indexing, or canonical signals block the page. | Does not directly explain post-click conversion issues. |
| Queries / impressions / CTR | Queries / impressions / CTR | Which search contexts the page enters and whether people click. | Does not alone prove order quality or profit. |
| GA4 landing page / ecommerce events | GA4 landing page / ecommerce events | When the Google tag and relevant events are correctly implemented, read landing-page, add-to-cart, and purchase evidence after the click. | Does not prove that the URL is indexed, entered a query scene, or has search demand; return to Search Console and URL Inspection for those questions. |
Search Console clicks and GA4 sessions are different measures. Compare ecommerce events only after the tags and events are implemented correctly; do not combine clicks or sessions into an order forecast.
Google describes crawling, indexing, and serving as separate parts of Search. Reviewing and improving a page is the team’s work loop, not a fourth Google stage or a promised outcome.
Follow the checks from URL discovery to user clicks
Crawl to Click Flow: inspect each layer from URL discovery to user clicks
This puts URL Inspection, sitemap, canonical, and rendered HTML on one path. In Search Console URL Inspection, paste the full URL; indexed version is Google’s stored view, while live test only checks whether the current page may be crawlable and eligible for indexing. Click a step to see the beginner misread, the action to take, and the evidence to copy. Do not collapse these tools into one vague “Google gave no traffic” problem.
Beginner flow
- Tools and reports
- Sitemaps + internal entry paths
- Beginner misread
- Assuming sitemap submission means Google will prioritize crawling and indexing.
- What to do
- Confirm the URL is in the sitemap and give it stable internal links from home, collection, article, or product pages. A sitemap cannot replace internal links.
- Evidence to copy
- Copy: sitemap submitted/discovered state, entry page URL, anchor text, click depth, and orphan-page status.
- Tools and reports
- URL Inspection indexed version / live test
- Beginner misread
- Seeing live test pass and assuming the current page is indexed and ready for traffic.
- What to do
- Read indexed version and live test separately: indexed version is Google’s stored view, while live test checks whether the current version may be crawlable and indexable.
- Evidence to copy
- Copy: indexing state, last crawl, crawl allowed, page fetch, user-declared canonical, and Google-selected canonical.
- Tools and reports
- page source / rendered HTML
- Beginner misread
- Assuming search systems see products and body copy just because your browser does.
- What to do
- Compare source and rendered HTML: core title, products, explanatory copy, pagination, filters, and internal links should appear reliably.
- Evidence to copy
- Copy: whether core content appears in source or stable rendered output, missing modules, current page version, and latest visible change.
- Tools and reports
- canonical / Google-selected canonical
- Beginner misread
- Assuming Google must index the version you declared in canonical.
- What to do
- Compare user-declared canonical with Google-selected canonical. If Google chooses another URL, inspect duplication, parameters, content overlap, and internal-link signals.
- Evidence to copy
- Copy: primary URL, duplicate URLs, canonical tag, Google-selected version, and merge/strengthen/noindex/remove decision.
- Tools and reports
- Search Console Pages / Queries + GA4 landing page
- Beginner misread
- Assuming an indexed page without orders is still a technical problem.
- What to do
- First inspect queries, impressions, position, and CTR; if clicks exist but conversion fails, route the issue to page fit, CRO, PDP, pricing, or trust review.
- Evidence to copy
- Copy: query, impressions, clicks, CTR, average position, landing page engagement, add_to_cart, and purchase.
Record the search state for one URL
URL state lab: read the state clearly before deciding who investigates next
This turns crawl, render, indexing, and serving checks into a page-state record. Selections update only the exercise: they do not read Search Console, visit a real URL, submit a sitemap, request indexing, or change a page. A real investigation still needs the right owner to check the same page in the current system.
Page-state record
Identify the page state, then choose the report to read
Do not enter a full domain, query parameters, account, credential, order, customer, or query export. Use a page label or non-sensitive path with an evidence summary, acceptance metric, owner, review date, next action, important-page map, and candidate pages.
The record stays in this browser; exported JSON only exists in the file you download and does not connect to a platform.
URL state practice
This is a practice record, not a live Google crawler or account screenshot.
What your selected next step means
Choose a judgment first
Select the next move in the record, then review why it is safe or unsafe.
A passing live test does not mean indexed
The live test reads the current page; the indexed version reads Google’s stored version. Neither guarantees the URL will appear in Search results.
Page appearance cannot rule out a soft 404
Read the Page indexing report reason and HTTP response, then check whether a real replacement exists. A complete-looking page is not enough to determine the state.
A sitemap does not replace an internal entry path
A sitemap is one discovery clue. Important pages still need a path through the site and remain subject to crawl, indexing, and page-value decisions.
Go
Start with evidence for the same URL
Record its report state, internal entry path, and review window before choosing who follows up. A live test or sitemap submission alone cannot prove indexing or ranking.
Current URL state
- What this state says
- Google knows the URL, but it has not been crawled and added to the index. One status alone does not prove a page-quality problem.
- Check first
- Read the reason, scope, and source in the Page indexing report; then check the sitemap record and stable internal entry for this URL.
- What it does not prove
- A crawl request or sitemap submission does not make indexing immediate and cannot replace page value or an internal path.
- Next check
- Record the entry page, sitemap state, and review window. If needed, have the technical or content owner check the same URL again.
- What this state says
- Google crawled the page but is not currently keeping it in the index. Separate checks for duplication, canonical, noindex, page job, and content value.
- Check first
- Read the Page indexing report reason, then use the indexed version in URL Inspection to check Google-selected canonical and latest crawl information.
- What it does not prove
- Do not start with a mass rewrite, publish more near-duplicates, or record a passing live test as indexed.
- Next check
- Have the page owner compare its job, duplicate URLs, and primary-version signals before choosing to strengthen, merge, canonicalize, or keep it unindexed.
- What this state says
- A page that looks normal may still be classified as a soft 404. A truly removed page with no replacement is a different case; appearance alone cannot decide it.
- Check first
- Read the Page indexing report reason and HTTP response, and check whether there is a real replacement. Ask the page and technical owners to decide.
- What it does not decide
- This exercise does not choose between 404, redirect, restoration, or removal. Google recommends 404 for a truly removed page with no replacement.
- Next check
- Record whether the page still has a business use, whether a genuine replacement exists, and who will confirm. Do not change its URL or redirect here.
- What this state says
- A shopper screenshot can look complete while Google’s tested or crawled page is missing copy, products, links, canonical, or resources.
- Check first
- Separate indexed version and Test live URL in URL Inspection, then compare the screenshot, HTML, resources, and JavaScript output in View tested page or View crawled page.
- What it does not prove
- A live test speaks to current crawl and parsing visibility. It does not replace indexed-version, duplicate, quality, or ranking checks.
- Next check
- Give missing core elements and the latest visible page change to the theme or technical owner. Do not turn a rendering issue into keyword work.
- What this state says
- The user-declared canonical and Google-selected canonical can differ. Check duplicate URLs, parameters, content overlap, and internal-link signals.
- Check first
- Start with URL Inspection’s indexed version. Google-selected canonical is indexed data; a live test cannot predict the final primary version.
- What it does not prove
- Canonical is a preference signal, not a command, redirect, or guarantee of indexing.
- Next check
- List duplicate or alternate URLs and internal-link signals, then have a technical owner decide whether any later change is needed.
- What this state says
- Search Console has no impression record for the selected page, query, and date range. That is a report observation, not proof that market demand is zero.
- Check first
- Review a complete comparison window by page and query, then check page job, live SERP, country, device, and internal links. Use customer or support questions as additional demand evidence.
- What it does not prove
- Indexing does not guarantee that a page will appear for every query. Missing query or impression rows do not prove that nobody searches.
- Next check
- Record no impressions, impressions with few clicks, and indexing status as separate observations. Then review the keyword, page-job, and result-promise evidence.
Choose the evidence surface
- How to read it
- Start with the reason, scope, and source. The report shows a limited set of example URLs, so an unlisted URL is not verified by its absence.
- How to read it
- Read Google’s latest indexed version, including latest crawl, discovery, indexing, and Google-selected canonical information.
- How to read it
- Check whether the current page can be crawled and parsed. This test does not check every indexing condition.
- How to read it
- Compare rendered screenshot, HTML, resources, and JavaScript output to see whether core content is present.
- How to read it
- Check the sitemap and stable links from navigation, collections, products, or related articles. A sitemap alone does not guarantee indexing.
Record evidence for each search stage
The state map is not done when it is drawn. Each state must point to backend paths and fields, otherwise the team falls back to editing titles whenever ranking is weak. Use this table in your notes: write the backend surface, fields, what it proves, and the conclusion it does not support.
Turn crawl, understanding, and ranking into reviewable fields
Not discovered / weak entry path
- Where to look
- Search Console -> Sitemaps; URL Inspection; Shopify Content → Menus (called Navigation in older interfaces); collection, hub, and product-page internal links.
- Fields to record
- URL, sitemap submitted / discovered state, last submitted time; entry page, anchor text, click depth, and orphan status; whether the URL appears in home navigation, collections, related products, or articles.
- Can prove
- Proves whether search systems and the site structure have a real path to discover the page.
- Do not conclude
- Misreading an entry-path problem as a title problem, or stopping at sitemap submission.
- Next route
- Add internal links and sitemap records first; if entry paths are messy, move into Technical SEO advanced crawl budget / URL governance.
Unstable crawl or render
- Where to look
- URL Inspection -> Live test; server logs; page source / rendered HTML; robots.txt; redirect chain; theme template.
- Fields to record
- HTTP status, robots allowed / blocked, redirect target, and crawl time; whether copy, products, pagination, filter links, and canonical appear in source or stable rendered output; current version, latest visible change, and failing URL sample.
- Can prove
- Proves the page is not only browser-accessible for users, but also readable for search systems.
- Do not conclude
- Assuming crawl is fine because the page opens in a browser; treating rendering failure as a keyword problem.
- Next route
- Fix robots, status, redirects, template output, and core-content visibility before moving into technical SEO basics.
Crawled but not indexed
- Where to look
- Search Console -> Indexing -> Pages; URL Inspection; canonical / noindex / duplicate checks; content and collection-page job table.
- Fields to record
- Index status, Google-selected and user-declared canonical, noindex; duplicate and primary URLs, page job, and whether it deserves its own URL; strengthen, merge, canonicalize, noindex, or remove decision and review date.
- Can prove
- Proves whether the issue is page value, duplication, canonical signals, or Google choosing another primary version.
- Do not conclude
- Treating every unindexed page as a technical failure.
- Next route
- Decide page survival and primary version first; complex parameters, pagination, and duplicate issues belong in Technical SEO advanced.
Indexed but weak impressions / clicks
- Where to look
- Search Console -> Performance -> Search results; Pages / Queries / Countries / Devices; manual SERP review; GA4 landing page.
- Fields to record
- URL, query, impressions, clicks, CTR, average position, country, device; SERP type, title link, snippet promise, competing pages, current ranking URL; landing-page engagement, add_to_cart, purchase, and support questions.
- Can prove
- Proves whether the page enters the right query scenes, whether searchers click, and whether post-click fit holds.
- Do not conclude
- Collapsing low impressions, low CTR, and low conversion into one ranking problem.
- Next route
- Low impressions go to keyword basics; low CTR to title/snippet and page promise; low conversion to CRO / PDP / pricing paths.
Search Console clicks and GA4 sessions are different measures. Compare ecommerce events only after tags and events are implemented correctly; do not combine clicks or sessions into an order forecast.
For discovery and crawling issues, first check entry paths, status codes, and rendering in this lesson. Complex crawl budget, duplicates, and parameter URLs belong in advanced technical SEO. When a page is indexed but has no impressions, review the search context in keyword basics. For impressions with few clicks, check the title, snippet, and result-page promise.
Choose the first check based on site history
Site history helps choose the first evidence source. A new site first proves that core pages have stable entry paths and crawlable versions; an established site first looks for conflicts among similar URLs, historical versions, or internal-link structure. At either age, the current URL state and evidence matter more than the site’s age for the next step.
New sites and established sites need different first checks
New site
- Focus
- Stable discovery, clear structure, base page quality, Search Console setup.
- Wrong move
- Expecting mature-site ranking speed.
- First check
- Whether core pages have entries in navigation, collections, sitemap, and links.
Established site
- Focus
- Duplicate content, old structure, low-value pages, canonical signals, internal competition.
- Wrong move
- Solving every traffic issue by adding more pages.
- First check
- Which pages should be strengthened, merged, redirected, noindexed, or removed.
Four versions of “no ranking,” four first checks
Treat each row as a diagnostic starting point , not a final cause. Perform that row’s first check; only move to the next layer when evidence rules it out. This keeps “no ranking” from turning content, technical setup, internal links, and titles into simultaneous guesses.
Four search problems and what to check first
| Item | What you see | Check first |
|---|---|---|
| New page | A new product page has no traffic after two days. | Check whether the URL was discovered and whether it appears in the sitemap and collection links. No traffic after two days does not mean the page failed. |
| Crawled but not indexed | The page says Crawled - currently not indexed. | Check duplication, thin value, canonical conflict, and page job before choosing to strengthen, merge, canonicalize, noindex, or remove it. |
| Indexed, no impressions observed | No impressions appear for the selected page, query, and Search Console date range. | Check the page and query scope, live SERP, customer questions, page job, and internal support. Record “no impressions observed”; this alone does not prove that nobody searches. |
| Impressions but few clicks | The page has impressions but a low CTR. | Compare query, result-page layout, title link, snippet promise, and first screen. Do not blame the sitemap for a click problem. |
Quick check
A page has no ranking. What comes first?
This check blocks a bad reflex: editing the title whenever ranking is absent. Choose the action you would take, read the feedback, then decide whether to move into keyword basics.
Quick check
Self-check not answered
What to confirm before moving to the next lesson
Before moving on, leave one core URL with a state, evidence, owner, and review date . The next lesson’s keyword and page work can then build on the current evidence.
Confirm the state and evidence before changing the page
| Stop here | Go |
|---|---|
Editing the title before checking whether the page was discovered, crawled, rendered, or indexed. | Identify the current state and assign the next check to the owner for that layer. |
Submitting only a sitemap without a stable path from navigation, a collection, or a related page. | Important URLs have a reviewable internal entry path and an evidence source. |
Treating a crawl as proof of indexing, or one live test as the final decision. | Record Google’s stored version and the current live test separately. |
Calling an indexed page with no impressions a technical failure or proof that nobody searches. | Separate “no impressions observed” from “impressions but few clicks,” then check scope, the SERP, and customer evidence. |
Leaving out the owner, a clear action, or a review date. | Record evidence, the next action, owner, and review date for each important URL. Route post-click issues to page, product, pricing, or trust review. |
Does this URL record meet the review conditions?
Complete required fields and format checks first. If a specific issue appears below, follow that guidance. Filling the form alone does not make the diagnosis ready.
The important-page map needs 5–10 lines, each with a page label or non-sensitive path and link relationship. Add at least three candidate pages marked orphaned, duplicate, or low value. Do not enter full domains, URLs, queries, fragments, emails, or credentials.
Important pages generally need both a sitemap record and a stable navigation or internal-link path. “Removed” is valid only when the selected state is soft 404 and the page is truly removed with no replacement.
Record which evidence came from Google’s stored version and which came from the current live test. Passing the live test does not mean indexed.
Choose the state, entry path, and review record for the same page before deciding what to change.
Required fields, page map, candidate labels, entry evidence, separate indexed/live readings, and a safe next-step choice have passed. After a fix, you may record one Request indexing request and review it on the chosen date; it is still no guarantee of indexing or ranking.
Next reading
Once the URL state is clear, continue into SEO and keyword judgment.
Carry the state, evidence, owner, and review date into SEO basics and keyword research. A page opening in a browser does not establish its search visibility.
- SEO basics: define what organic search needs to solve: Understand search systems and user value before deciding whether a URL deserves more work.
- Keyword research: connect search terms to page jobs: Once page state is clear, use queries, search intent, and page type to choose which page should serve the task.
Check these six points before moving on
- You can distinguish crawling, indexing, and ranking, and know rendering is a separate check.
- You know publishing a page does not mean a search system will find it.
- You understand that site structure and internal links affect discovery and page relationships.
- You know a sitemap does not guarantee crawling or indexing.
- You know that not every page needs its own index entry.
- You can name common differences between a new site and one with an established history.
No checkpoint finished in this lesson yet. Start with “Go to the exercise”.
Self-check not answered
Search Console state FAQ
- What does Discovered - currently not indexed mean?
Google knows the URL, but it has not been crawled or added to the index. Check internal entry paths, sitemap, link depth, and whether the page deserves attention before editing its title. A 7–28 day review window is one planning example, not a promise about indexing or ranking.
- Should I rewrite a page as soon as I see Crawled - currently not indexed?
First check duplication, thin value, canonical selection, noindex, and whether the page has a clear job. A crawl does not mean the page belongs in the index. Use the evidence to choose whether to strengthen, merge, canonicalize, noindex, or remove it; do not just add keywords.
- Why is my page still not indexed after I submitted a sitemap?
A sitemap is a discovery clue, not an indexing promise. The page still needs to be crawlable, understandable, connected to the site, and useful as its own page. Check URL Inspection, the Page indexing report, internal links, canonical, noindex, duplication, and page job.
- What is the difference between URL Inspection live test and indexed version?
The indexed version reflects Google’s most recently stored version; the live test checks whether the current page may be crawled and parsed. Record last crawl, page fetch, crawl allowed, user-declared canonical, Google-selected canonical, and rendered HTML separately. Passing the live test does not mean indexed or shown.
- Should I request indexing every time I edit a page?
Do not treat it as a routine button. After an important fix or for an important URL, you may request indexing once and record the change, request date, expected state, and next review date. It does not replace internal links, sitemap, page quality, or follow-up checks, and it does not guarantee indexing.
- If a page is indexed but gets no impressions, is it a technical or keyword issue?
Confirm the page, query, country, device, and date range, then review the live SERP, page job, customer questions, and internal links. No impressions in Search Console do not prove that demand is zero. Keep “no impressions observed” separate from “impressions but few clicks,” then choose whether to review keywords, title and snippet, or post-click fit.
Sources
Sources: 8Last checked
Google How Search Works (opens in a new tab)Checked
Supports
Search involves separate discovery, crawling, indexing, and serving stages.
This source cannot prove
It does not guarantee that a particular page will be crawled, indexed, or shown.
URL Inspection tool (opens in a new tab)Checked
Supports
Use it to inspect one URL’s indexed version and current live test.
This source cannot prove
A passing live test does not prove indexing, ranking, or traffic.
Sitemaps overview (opens in a new tab)Checked
Supports
A sitemap can help search systems discover URLs.
This source cannot prove
It cannot replace internal links, page value, or an indexing decision.
robots.txt introduction (opens in a new tab)Checked
Supports
robots.txt controls crawling.
This source cannot prove
Do not use it as a general method to hide pages or implement noindex.
Canonical URL guidelines (opens in a new tab)Checked
Supports
Canonical expresses a preferred version; compare it with Google-selected canonical and other signals.
This source cannot prove
It is not a forced redirect and does not guarantee indexing of the preferred URL.
Page indexing report (opens in a new tab)Checked
Supports
Use it to inspect index status and reasons for important URLs.
This source cannot prove
Not indexed is not automatically an error; duplicates, intentional noindex, and truly removed pages can have valid reasons.
Search Console Performance report (opens in a new tab)Checked
Supports
Compare clicks, impressions, CTR, and average position by page, query, country, or device, and choose the date range.
This source cannot prove
A missing query or impression row does not prove that market demand is zero; Search Console clicks are not GA4 sessions.
Shopify: Menus and links (opens in a new tab)Checked
Supports
Manage menu links under Content → Menus in the current Shopify admin; theme placement is configured separately.