22 parts · 4 checkpoints · 3 free / 19 member parts →
Shopify technical SEO: why a page is missing from search
Your product page opens, but is missing from Google Search. Start by checking whether it is accessible, crawlable, free of an accidental noindex, and represented by the intended main URL in Google’s indexed record. Technical SEO uses observable evidence to locate a blocker; it cannot guarantee indexing or ranking. This lesson is for Shopify owners and content leads who need to review collection, product, or guide URLs and hand a clear record to the right person.
Key point Keep one URL in view
A page that a shopper can open, a crawler that can request it, and a URL that Google has indexed are three different states. Record them separately before deciding whether to inspect access, crawling, indexing, or the main version.
What this lesson answers
The controls answer different questions. Opening a page in your browser proves only that this request succeeded; check login restrictions, returned content, and Google’s access separately; crawl rules decide whether a crawler can request it; noindex asks that it stay out of the index; canonical signals a preferred version among similar URLs; a redirect moves an old address to a relevant new one; and a sitemap helps discovery. None of these controls guarantees indexing or ranking.
Use a commuter tumbler product page as the teaching example. Its sample capacity is 20 fluid ounces (20oz). It may answer capacity, cup-holder fit, and shipping questions, yet an accidental noindex can still obstruct its search entry. Removing noindex does not fill missing product information. Write down the page’s purpose, then check the technical state so a content gap and a setting blocker do not get mistaken for one another.
Indexed record and live test
Search Console URL Inspection separates indexed data from a live test. The indexed record reflects the last state Google processed and can show Google’s selected canonical. A live test checks whether Google can access and read the page now. A live test cannot predict which canonical Google will ultimately choose , and the two views do not replace one another. Save the dates and results; if they differ, compare the last crawl with the current response before calling it a new fault.
Robots.txt affects crawl requests; noindex asks to keep a page out of the index; canonical is a preferred-version signal; redirects move old addresses; and sitemaps help discover URLs. Canonical and redirects are stronger signals than sitemap inclusion, while a crawler must be able to read a page to see noindex. These signals have different strengths and none is an automatic guarantee.
A new setting may need a later crawl and indexing update. One successful live test does not mean the page is indexed. For an important product or collection, keep the previous file, URL, status code, and recovery owner before arranging a change.
The page is fixed, so why is the index record still old
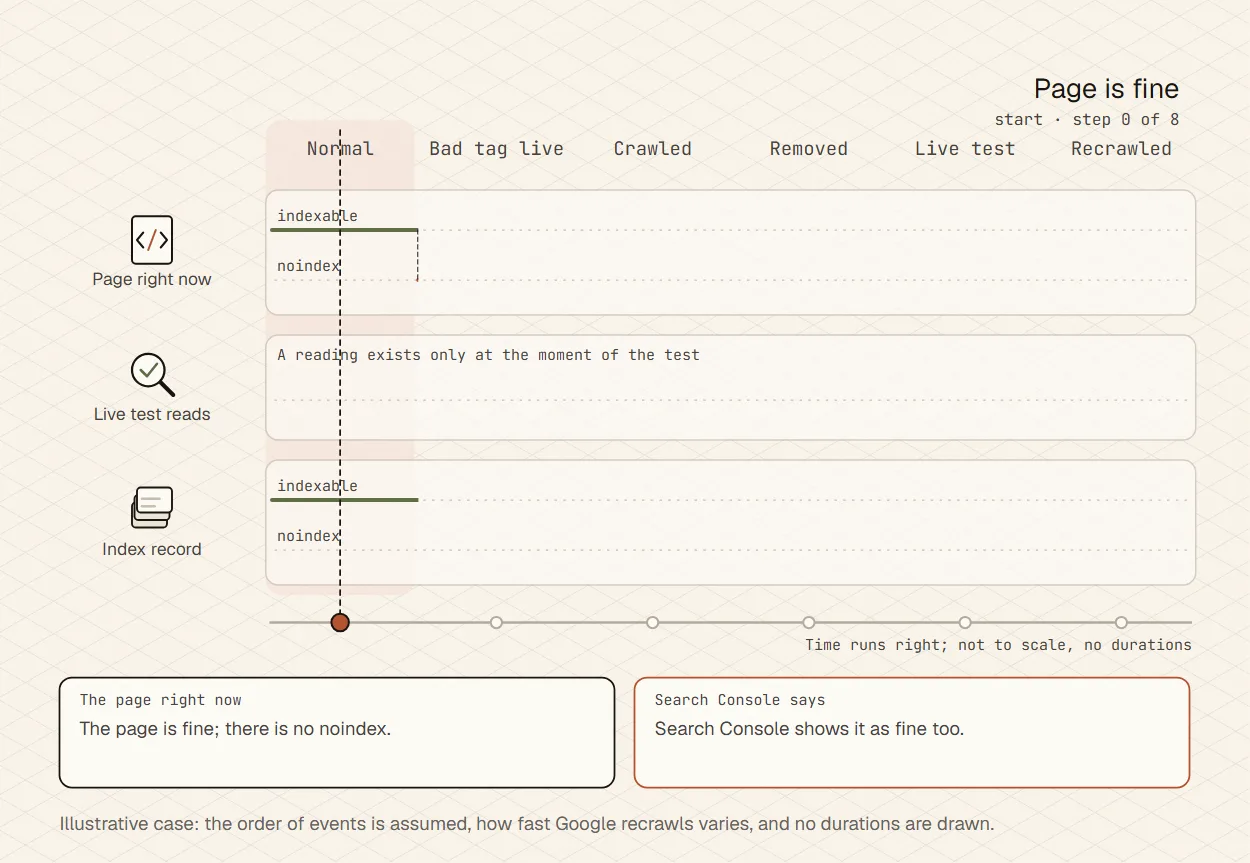
As text: the whole walk-through
- noindex by mistake A release adds noindex by mistake. The page says noindex right now; Search Console knows nothing yet.
- Record says noindex Google crawls the page and the index record becomes noindex. From now on the record and the page are two different things.
- Record says noindex The live test reads noindex, matching the record: the problem is confirmed.
- Record says noindex Before changing anything, save the old file, the URL and the status code, and name who rolls back.
- noindex removed Remove noindex. The page is fine now, but the index record has not changed.
- Live test passes The live test passes: right now the page can be reached and read. That says nothing about being indexed.
- Live test passes Compare the last crawl time with the current response: the record was taken before the fix. It is not a new fault.
- Record updated Only the next crawl updates the index record. Now it is really fixed.
Illustrative case: the order of events is assumed, how fast Google recrawls varies, and no durations are drawn.
What should you do first?
Self-check not answered
Free account to read · Parts 3-21 · 19 parts
Members: URL-family review and a saved work record
Record a real page state, its signals, an owner, and a recheck condition in this browser.
This part includes
- Compare five controls against a real URL family
- Keep Google’s selection separate from a live access check
- Export a handoff record with a recheck condition
An account is free; sign in to read this part.
Checking your membership…
No checkpoint finished in this lesson yet. Start with “Go to the exercise”.
Self-check not answered
FAQ
- What is Shopify technical SEO, and what should I check first?
Technical SEO checks whether search engines can discover, request, and understand a page, and whether indexing or canonical signals exclude it by mistake. Start with one important URL: accessibility, source, crawling and indexing state, then sitemap, canonical, and internal links. Content fit needs a separate check; a technically sound page is not guaranteed to rank.
- What is the difference between robots.txt and noindex?
Robots.txt controls whether a crawler may request a path; noindex asks for a page to stay out of the index. A robots-blocked URL may still appear in search, and Google may be unable to read its noindex. Inspect the returned HTML or response header, the page purpose, and applicable rules before editing. These controls are not interchangeable.
Next reading
After technical blockers are clear, check whether content and data hold together.
Compare content fit and later observations for the same page. Keep Search Console, GA4, and order records in their own scopes; a query is not an identifiable visitor-to-order trail.
- Content SEO: check whether the page answers the demand: After technical settings are clear, check whether page content, search task, and product facts match.
Sources
This technical SEO review turns official technical docs into beginner blocker triage. It does not promise indexing or ranking after submission, fixes, or scores.
Sources: 12Last checked
Google canonical documentation (opens in a new tab)Checked
Supports
Used to explain canonical URL signals and consistency with links, sitemap, and redirects.
Google robots.txt documentation (opens in a new tab)Checked
Supports
Used to explain crawl control, not index removal.
Google sitemaps documentation (opens in a new tab)Checked
Supports
Used to explain discovery support without indexing or ranking guarantees.
Google noindex documentation (opens in a new tab)Checked
Supports
Used to explain that noindex must be crawlable to be read and should not be mixed with robots blocking.
Shopify robots.txt documentation (opens in a new tab)Checked
Supports
Used to explain that Shopify default robots.txt is usually enough and incorrect edits can lose traffic.
Shopify sitemap documentation (opens in a new tab)Checked
Supports
Used to explain Shopify-generated sitemaps and that submission supports discovery rather than promising indexing.
Google for Developers: Faceted navigation (opens in a new tab)Checked
Shopify robots.txt.liquid documentation (opens in a new tab)Checked
Supports
Explains how a custom template replaces generated robots.txt output and why the rendered file needs comparison.
Shopify URL redirects documentation (opens in a new tab)Checked
Supports
Used to explain that redirects require a broken source, relevant target, market path, and cache boundary; they are not a general cleanup button.
Google URL Inspection help (opens in a new tab)Checked
Supports
Separates the indexed record from a current live test and explains their limits.
Google Page indexing report help (opens in a new tab)Checked
Supports
Explains indexing and exclusion states; valid exclusions need not all become indexed.
Google for Developers: Robots txt spec (opens in a new tab)Checked